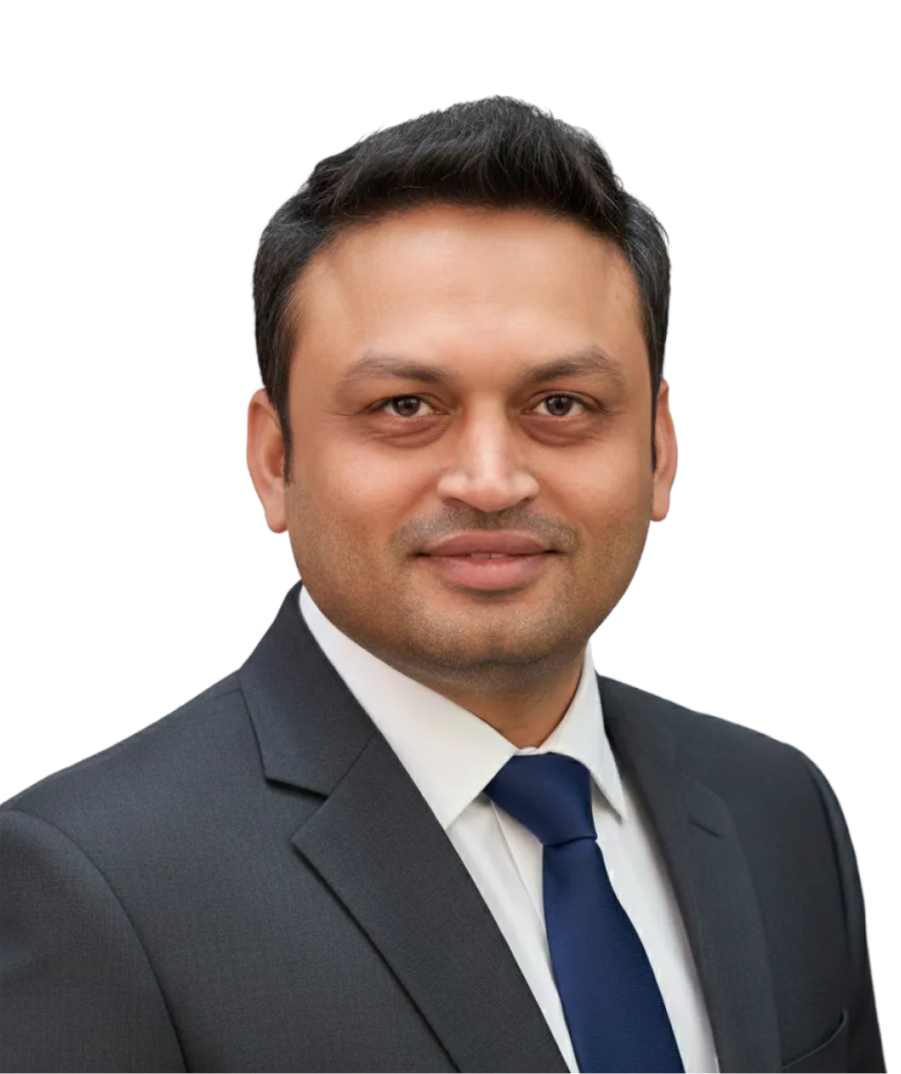
For sixteen years ,MotadataCo-Founder and CEOAmit Shingalahas focused on one question that still troubles enterprise IT: why does it take so long to go from spotting a problem to resolving it? His answer has shaped an AI-driven platform that brings observability and IT service management together.
Ask most IT operations leaders what slows their teams down, and the answer is rarely a lack of data. Modern enterprises collect more metrics, logs, and alerts than ever before. The trouble is that the information lives in too many places, arrives in too great a volume, and passes through too many hands before anyone acts on it.
Amit Shingala has watched this pattern for his entire career. When he and his co-founder started Motadata in Ahmedabad in 2010, enterprises were already juggling separate tools for network, infrastructure, and log monitoring. The tools have changed since then, and environments now span data centers, clouds, and remote sites, but the underlying problem has only grown.
“Enterprises do not suffer from too little information. They suffer from information that never comes together in time for someone to act on it.”
Here are the four problems Amit sees most often, and how Motadata was built to solve them.
Why Do IT Teams Still Work Across So Many Tools?
In a typical enterprise, the network team, the server team, and the application team each run their own monitoring products. When a business service slows down, engineers open several consoles, compare timestamps by hand, and argue over whose layer is at fault. Precious time goes into assembling the picture before anyone can start fixing the problem.
Motadata’s answer is ObserveOps, a unified observability platform that brings log management, hybrid infrastructure monitoring, network observability, network configuration management, application performance monitoring, and real user monitoring into one place. Every team works from the same data and the same view of the environment, which removes the handoffs between tools before they start.
Why Do Alerts Overwhelm the People Meant to Act on Them?
More monitoring usually means more alerts, and more alerts often mean less attention for each one. Operators learn to tune out repeated warnings, and the one alert that signals a serious incident can get buried among hundreds of minor ones.
This is where the AI built into ObserveOps does its work. It detects anomalies in the behaviour of systems and cuts down the volume of redundant alerts that reach operators, so teams see fewer, more meaningful signals. Unlike many AI approaches, it does not require pre-training or a baseline calibration period before it becomes useful.
“If every alert looks urgent, none of them are. The job of AI in operations is to decide what deserves a human’s attention, and to do that from the first day, not after months of tuning.”
Why Does Finding the Root Cause Take So Long?
Even with a clear alert, the cause of an incident is often several layers away from the symptom. A slow application might trace back to a misconfigured switch or a saturated storage array. Without connected data, engineers work through each possibility one at a time.
Because ObserveOps holds network, infrastructure, application, and log data together, the platform can correlate events across those layers and assist with root cause analysis. Instead of starting from a symptom and guessing, teams start from a likely cause and confirm it.
Why Do Incidents Stall Between Monitoring and the Service Desk?
The most expensive delay, in Amit Shingala view, happens after a problem has already been detected. In many organizations, monitoring and IT service management belong to different teams using different tools. An alert fires, someone has to notice it, open a ticket, copy in the details, and route it to the right group. Every one of those steps adds time and room for error.
Motadata closes this gap by connecting ObserveOps with ServiceOps, its ITIL-aligned IT service management suite. When ObserveOps identifies an issue, it can raise it in ServiceOps as a ticket with its context attached. ServiceOps then brings in the rest of the service management process, including IT asset and configuration management and patch and deployment management, within a suite that holds PeopleCert ITIL 4 Tool Vendor Accreditation across 12 practices.
“Detection is only half the job. If an alert still depends on someone turning it into a ticket, you have built a delay into the worst moment of an incident. We wanted the path from signal to resolution to be one continuous flow.”
What Comes Next for IT Operations?
Amit Shingala expects the pressure on IT teams to keep rising as enterprises spread workloads across hybrid and multi-cloud environments, and as AI changes how software is built and supported. For Motadata, that means continuing to narrow the distance between the first sign of trouble and the resolved ticket, while taking more of the manual connecting work off operators’ plates.
Sixteen years after starting the company with a belief that India could build technology products for the world, he sees that mission and the product mission as the same thing.
“The measure of an operations platform is simple. Did the service stay up, and when it did not, how quickly did it come back? Everything we build has to move that answer in the right direction.”
Learn more about Motadata at motadata.com.
About the Author
Amit Shingala is Co-Founder and CEO of Motadata, an enterprise IT operations software company he started in Ahmedabad, India, in 2010. He leads strategy across ObserveOps, the company’s unified observability platform, and ServiceOps, its ITIL-aligned IT service management suite, and oversees Motadata’s partner-led growth across international markets. He writes and speaks on AI in IT operations, observability, and closing the gap between detecting incidents and resolving them.
Also Read :- CIO Times Magazine For More Information